DeepSeek-V4.1-Flash1M context, web search, and tool calling fully supported
Try it now
Next-generation AI infrastructure

Turn every unit of compute into intelligence

Model marketplace

Explore leading open-source and proprietary models. Deploy and start calling in minutes.

View all models

DeepSeek-V4.1-Flash

DeepSeek-V4.1-Flash is the smallest model in DeepSeek's new architecture family, with native multimodal visual understanding. It is a 552B-parameter MoE model built on the new Causal-Encoder-Decoder architecture, with asymmetric input and output: only 8B parameters are activated for input and 16B for output, at a cost well below other known models of the same size. The new architecture sharply compresses the KV cache, cutting HBM requirements to 1/4 and SSD requirements to 1/8 of the previous generation, which lowers the cost of agent workloads where cache-hit charges make up a large share. The model supports a 1M context window and up to 384K output tokens; thinking mode is on by default, with three effort levels (low, high and max) to match task complexity.

Try now
Product interface preview
1 / 2

Easy accessYour first model

Sign up for free credits and make your first call in minutes.

Access leading open-source and proprietary models through one API.

Get API Key
first_call.py
from openai import OpenAIclient = OpenAI(base_url="https://api.tokenfab.com/v1", api_key="your-api-key")resp = client.chat.completions.create(model="deepseek-v4-flash",    messages=[{"role": "user", "content": "hello, TokenFab"}])print(resp.choices[0].message.content)
Read docs ↗

Compute services

Elastic, reliable and secure compute, from shared inference to dedicated clusters.

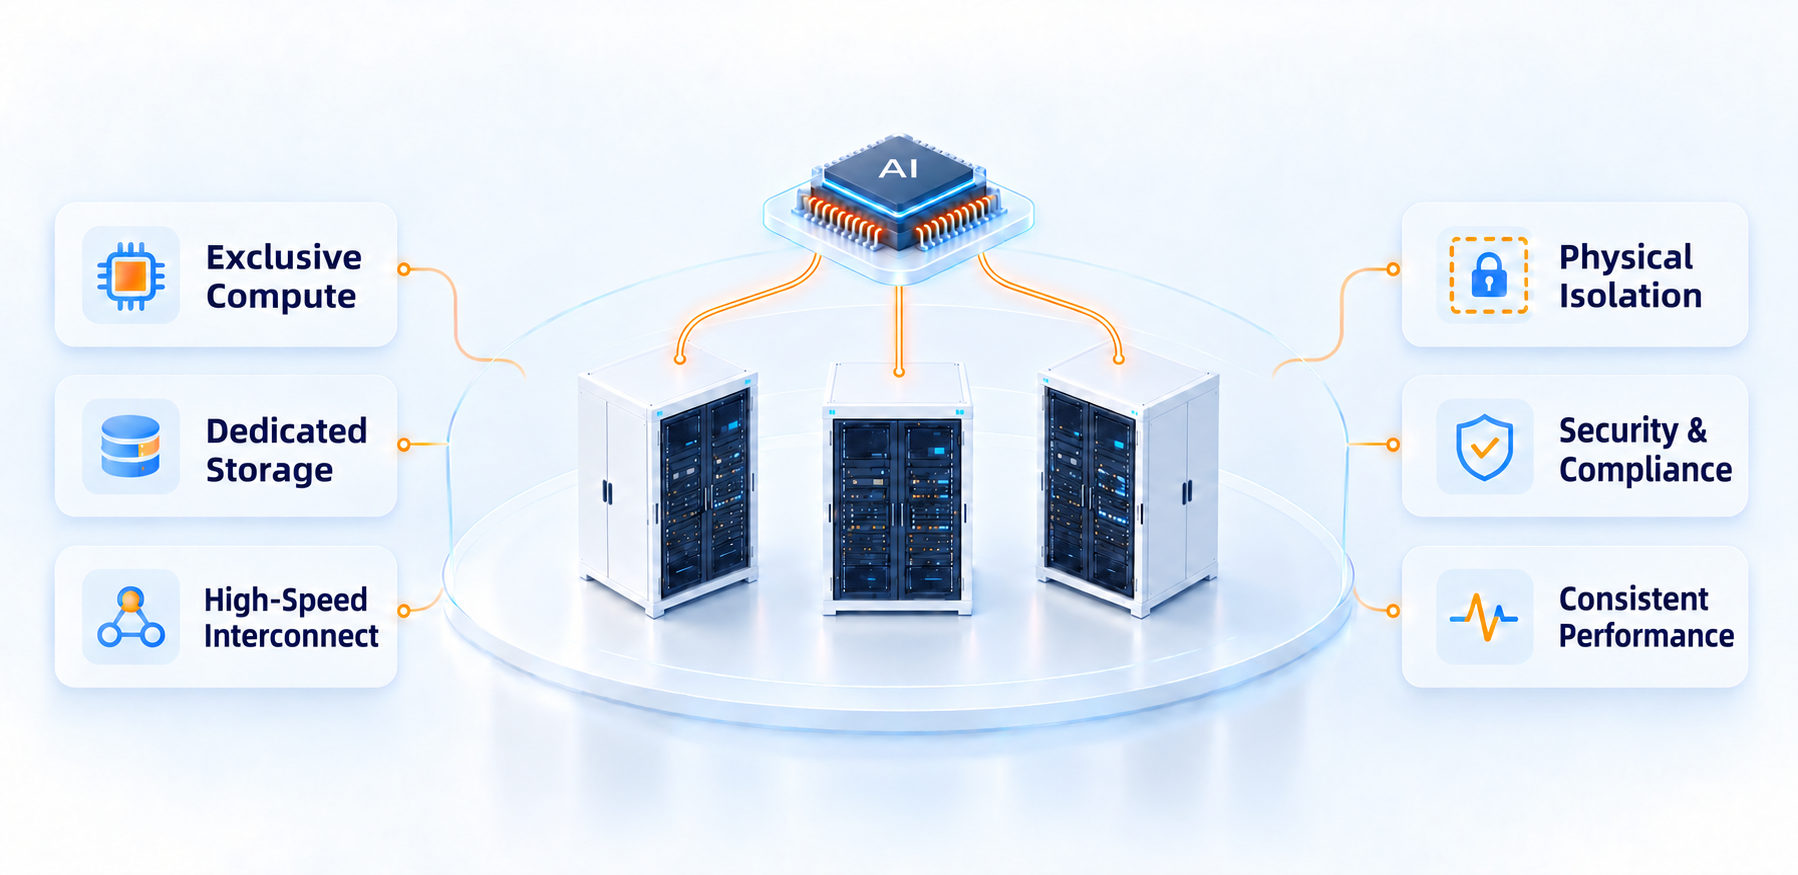
Dedicated clusters

Physically isolated, exclusive compute resources for security, compliance and consistent performance.

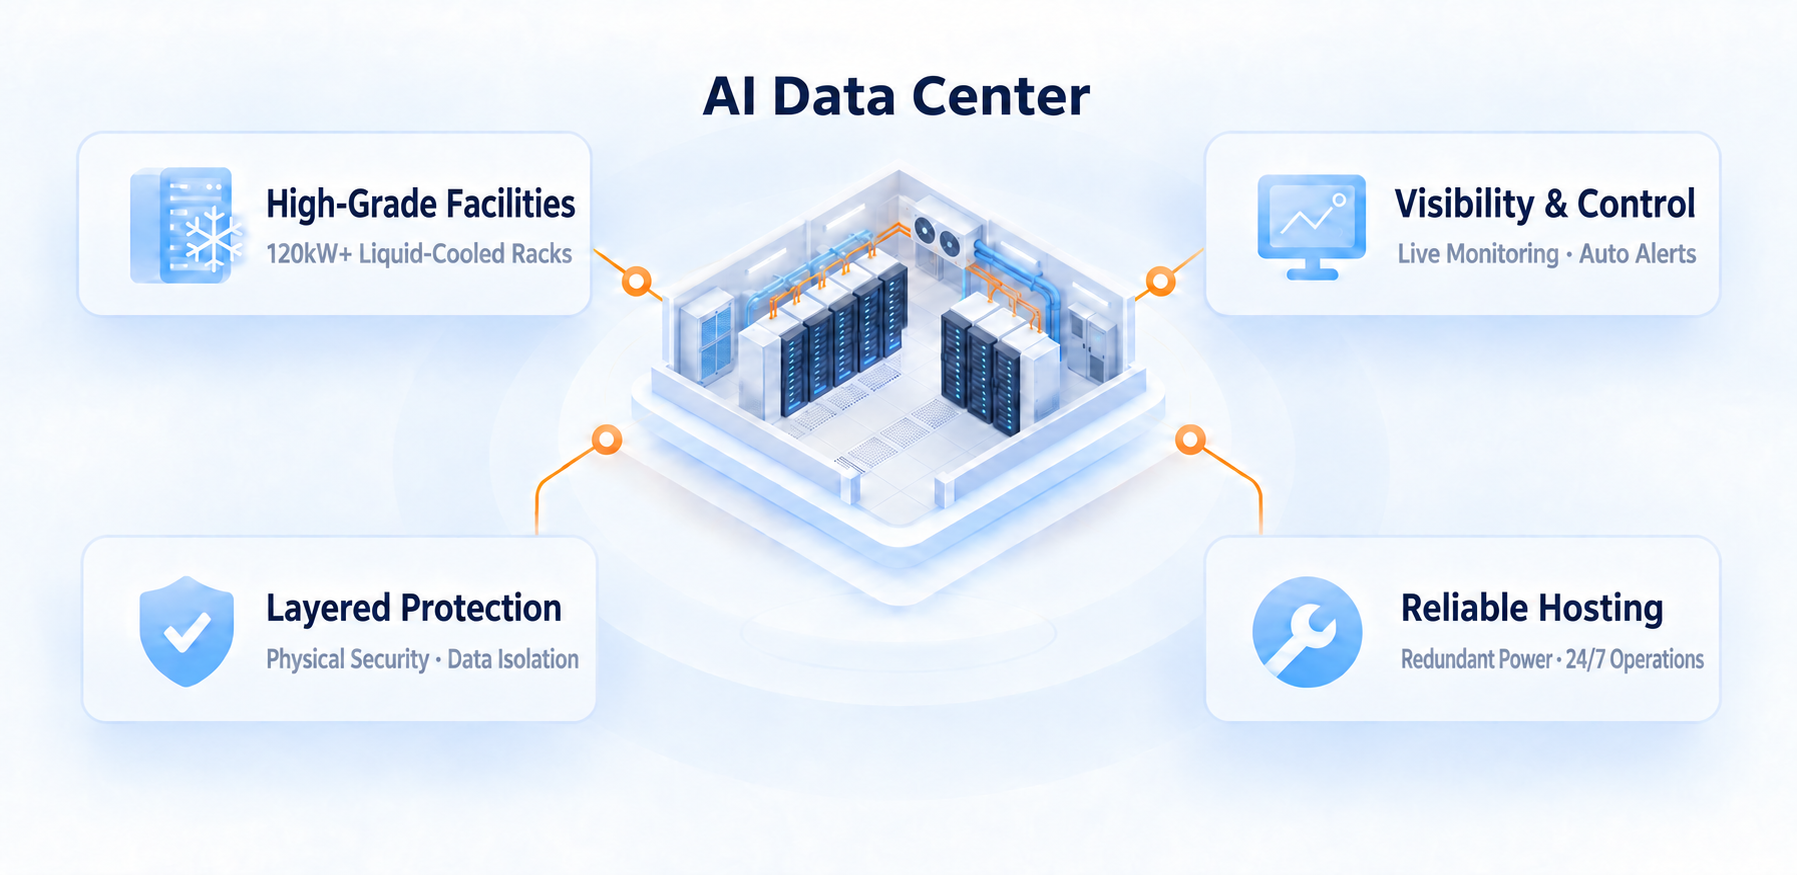
Compute hosting

Host GPU servers and clusters with 120kW+ liquid-cooled racks, redundant power and 24/7 on-site operations to bring AI assets into production faster.

MLPS Level 3Physical data isolation99.99% SLA24/7 support

Model production

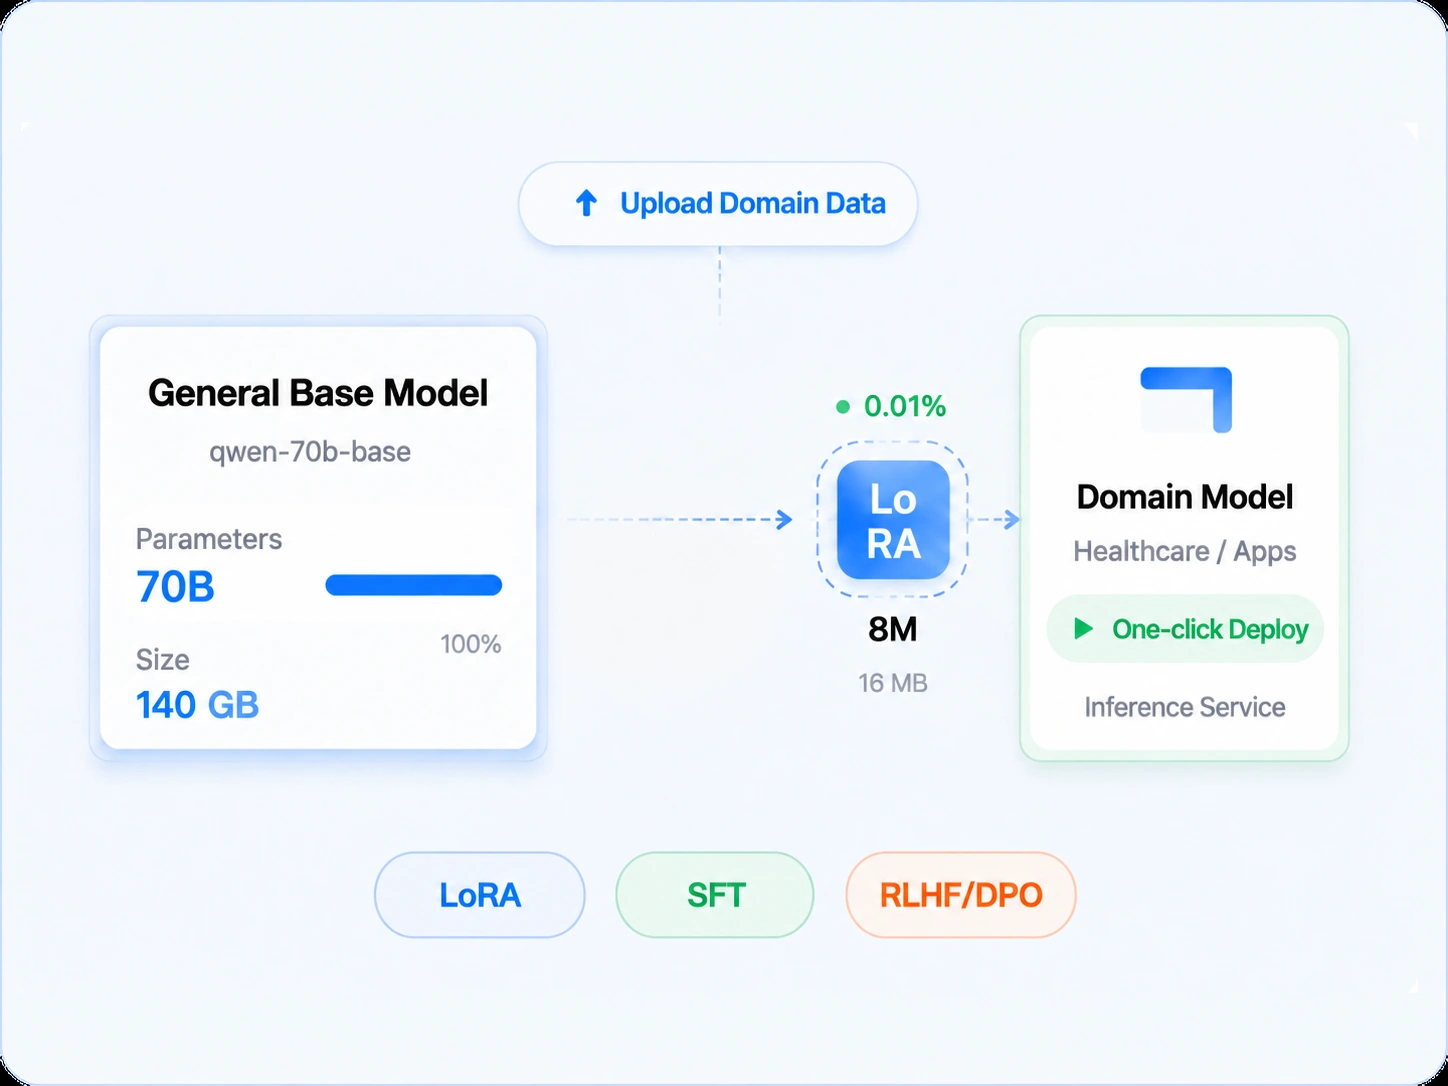
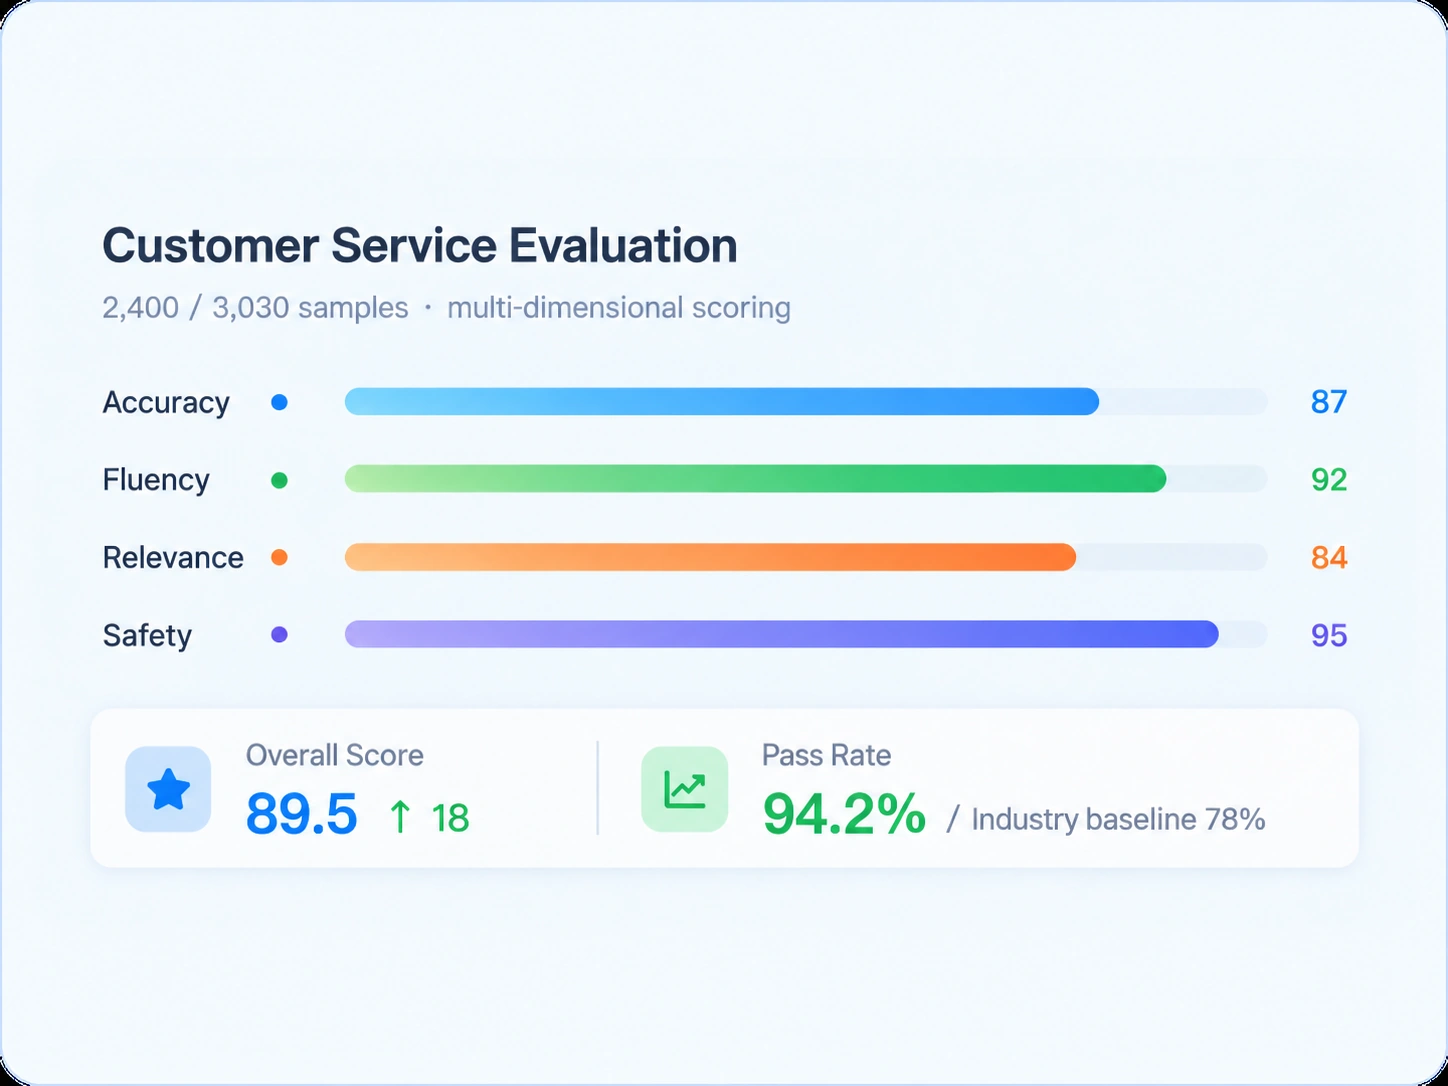
One workbench for distributed training, no-code fine-tuning, evaluation and deployment.

Model fine-tuning · Product interface preview

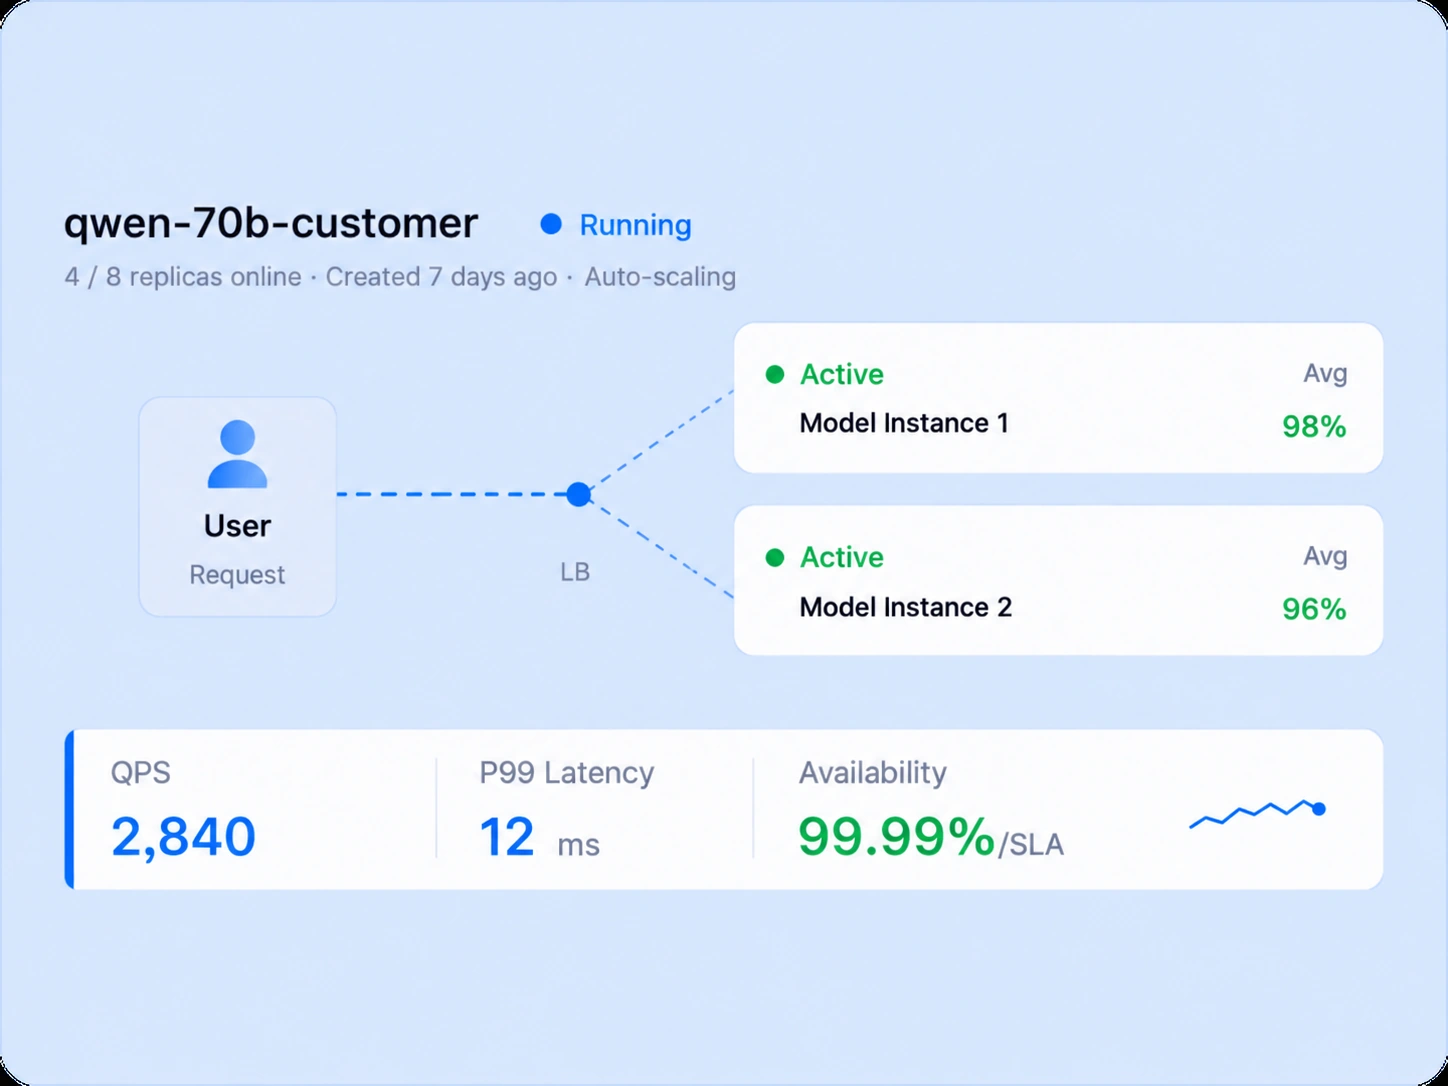
Model deployment

Deploy trained or fine-tuned models with high-performance APIs, low latency and automatic scaling.

Multiple modelsAuto scalingConcurrent APIsStreaming
Learn more
Model deployment · Product interface preview
Model evaluation · Product interface preview

Sign up and start your AI journey

Register now